
คู่มือใช้ MSEB ของ Google Research: เจาะลึกการสร้าง Sound Encoder
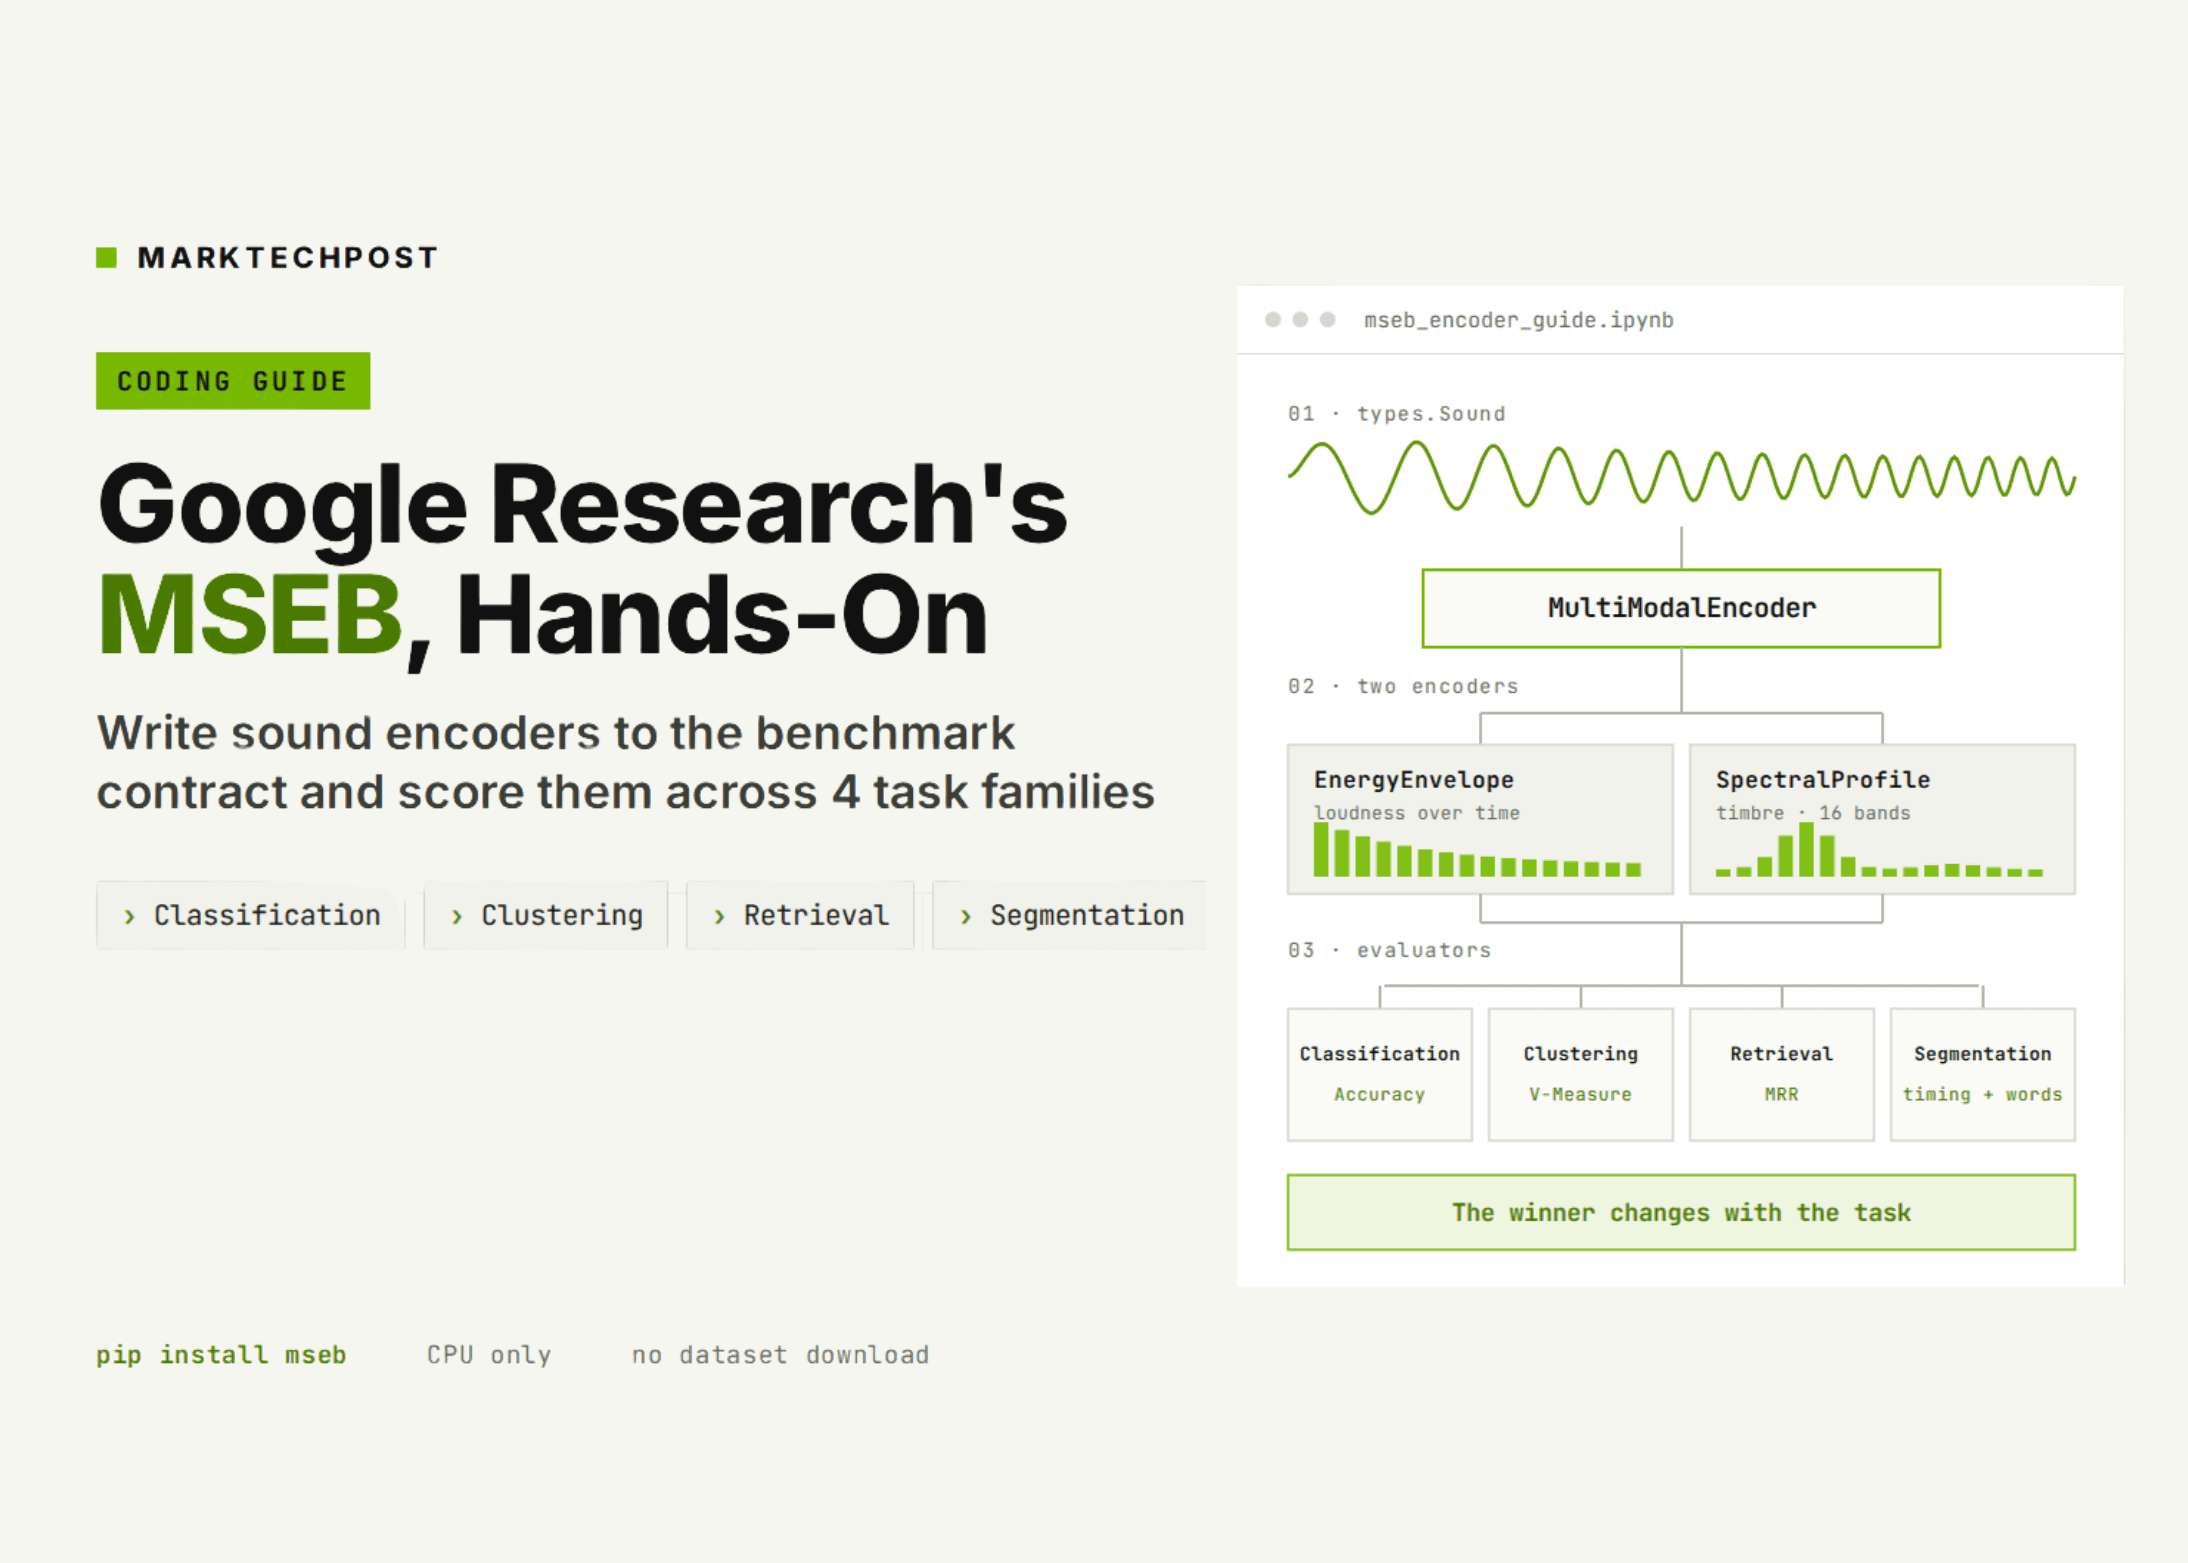
ในบทเรียนนี้ เราจะเจาะลึกการใช้งาน MSEB หรือ Massive Sound Embedding Benchmark จาก Google Research เพื่อทำความเข้าใจความหมายเบื้องหลังตัวเลขบนลีดเดอร์บอร์ดผ่านส่วนของตัวประเมินผล (evaluator surface) เราจะเริ่มจากการติดตั้งแพ็คเกจ ทำความเข้าใจโครงสร้างสามเลเยอร์ และเขียน encoder สองรูปแบบที่แตกต่างกันตามข้อกำหนดของเฟรมเวิร์ก ได้แก่ ตัวที่วัดความดังตามเวลาและตัวที่วัดระดับเสียง (timbre)
เราจะรันตัวประเมินผลทั้งการจำแนกประเภท (classification), การจัดกลุ่ม (clustering), การสืบค้น (retrieval) และการแบ่งส่วน (segmentation) บน embedding ที่สร้างขึ้นจากคลังข้อมูลสังเคราะห์ในโน้ตบุ๊ก โดยจะเรียกใช้ฟังก์ชันเมทริกซ์โดยตรงเพื่อดูเกณฑ์การให้คะแนน และปิดท้ายด้วยการประกอบ TaskMetadata สำหรับส่งผลงานจริง ผลลัพธ์จะแสดงให้เห็นว่า encoder ทั้งสองสลับอันดับกันตามประเภทภารกิจ ซึ่งตอกย้ำความสำคัญของ benchmark แบบหลายภารกิจ
import os
import sys
import json
import math
import traceback
import subprocess
import numpy as np
RESULTS = {}
BENCH = {}
def banner(title):
    print("\n" + "=" * 78)
    print(title)
    print("=" * 78)
def section(name):
    def wrap(fn):
        def run(*a, **kw):
            banner(name)
            try:
                out = fn(*a, **kw)
                RESULTS[name] = out if isinstance(out, str) else "ok"
                return out
            except Exception as e:
                RESULTS[name] = f"SKIPPED / FAILED -> {type(e).__name__}: {e}"
                print(f"\n[!] {name} did not complete: {type(e).__name__}: {e}")
                traceback.print_exc(limit=3)
                return None
        return run
    return wrap
banner("0. Install MSEB and map the three layers we will use")
subprocess.run([sys.executable, "-m", "pip", "install", "-q", "mseb==0.1.0"], check=True)
import mseb
from mseb import types, encoder as encoder_lib, evaluator as evaluator_lib, metrics
from mseb.evaluators import (
    classification_evaluator,
    clustering_evaluator,
    retrieval_evaluator,
    segmentation_evaluator,
)
print(f" mseb {mseb.__version__} | Python {sys.version.split()[0]} | numpy {np.__version__}")
print("\n MSEB is three layers, and a benchmark run walks down them:")
print(" types -> Sound, SoundEmbedding, Score, TaskMetadata: the shapes every task speaks")
print(" encoder -> MultiModalEncoder: the contract YOUR model implements")
print(" evaluators -> classification, clustering, retrieval, reranking, transcription, segmentation, ...")
print("\n evaluator entry points we will drive:")
for module, cls in [(classification_evaluator, "ClassificationEvaluator"),
                    (clustering_evaluator, "ClusteringEvaluator"),
                    (retrieval_evaluator, "RetrievalEvaluator"),
                    (segmentation_evaluator, "SegmentationEvaluator")]:
    print(f" {module.__name__.split('.')[-1]:28s} {cls}")
print("\n Everything below runs on CPU with no dataset download: we synthesise the audio.")
เมื่อติดตั้ง mseb แล้ว เราจะนำเข้าสามเลเยอร์หลัก: โมดูล types สำหรับโครงสร้างข้อมูลมาตรฐาน (Sound, SoundEmbedding, Score, TaskMetadata), โมดูล encoder สำหรับ MultiModalEncoder ซึ่งเป็นข้อกำหนดที่โมเดลต้องปฏิบัติตาม และแพ็คเกจ evaluators สำหรับชุดภารกิจต่างๆ ในที่นี้เราจะใช้เฉพาะตัวประเมินสี่ตัวที่ทำงานบน CPU ได้โดยไม่ต้องพึ่งพาตัวเร่งความเร็วหรือดาวน์โหลดชุดข้อมูลภายนอก
SR = 16000
@section("1. The type contract: Sound, SoundEmbedding, Score")
def type_contract():
    t = np.arange(SR) / SR
    waveform = (0.5 * np.sin(2 * np.pi * 440 * t)).astype(np.float32)
    sound = types.Sound(
        waveform=waveform,
        context=types.SoundContextParams(id="demo_000", sample_rate=SR, length=len(waveform),
                                        language="en_us", text="a 440 Hz tone"),
    )
    print(f" Sound id={sound.context.id!r} {sound.waveform.shape} @ {sound.context.sample_rate} Hz"
          f" -> {sound.size_bytes:,} bytes")
    embedding = types.SoundEmbedding(
        embedding=np.zeros((1, 16), dtype=np.float32), # (N, D): one utterance-level vector
        timestamps=np.array([[0.0, 1.0]], dtype=np.float32), # (M, 2): [start, end] in seconds
        context=sound.context,
        encoding_stats=types.EncodingStats(input_size_bytes=sound.size_bytes, embedding_size_bytes=16 * 4),
    )
    print(f" SoundEmbedding embedding{embedding.embedding.shape} timestamps{embedding.timestamps.shape}"
          f" -> {embedding.size_bytes} bytes")
    print(f" compression_ratio = {embedding.encoding_stats.compression_ratio:.5f}"
          f" ({1 / embedding.encoding_stats.compression_ratio:,.0f}x smaller than the audio)")
    print(" N embeddings and M timestamps: M == N is frame-aligned, M == 1 is utterance-level.")
    print(" `embedding` may also hold N strings instead of vectors - step 8 uses exactly that.")
    score = types.Score(metric="Accuracy", description="Overall classification accuracy",
                        value=0.875, min=0.0, max=1.0)
    print(f"\n Score {score.metric}={score.value} in [{score.min}, {score.max}] :: {score.description}")
    for bad, why in [(dict(metric="", description="d", value=0.5, min=0.0, max=1.0), "empty metric name"),
                    (dict(metric="m", description="d", value=0.5, min=1.0, max=0.0), "min > max")]:
        try:
            types.Score(**bad)
        except Exception as e:
            print(f" rejected at construction ({why}): {type(e).__name__}: {e}")
    return f"Sound {sound.size_bytes:,} B -> embedding {embedding.size_bytes} B"
type_contract()
ข้อกำหนดด้านประเภท (Type Contract) คือหัวใจสำคัญ เพราะทุกเลเยอร์จะสื่อสารกันผ่านโครงสร้างนี้ โดย Sound จะเก็บ waveform พร้อมบริบทที่จำเป็น ส่วน SoundEmbedding จะนิยามความสัมพันธ์ระหว่างเวกเตอร์และช่วงเวลา (timestamps) หากจำนวนเวกเตอร์เท่ากับช่วงเวลาจะเป็นการประเมินระดับเฟรม แต่ถ้ามีเวกเตอร์เดียวจะเป็นระดับคำพูด (utterance-level) นอกจากนี้ Score จะทำหน้าที่ตรวจสอบความถูกต้องของเมทริกซ์โดยอัตโนมัติ เพื่อป้องกันไม่ให้ข้อมูลที่ผิดพลาดหลุดไปถึงลีดเดอร์บอร์ด
class EnergyEnvelopeEncoder(encoder_lib.MultiModalEncoder):
    """Baseline: average energy in `n_bins` equal time slices. Loud/quiet, nothing about timbre."""
    def __init__(self, n_bins: int = 16):
        super().__init__()
        self.n_bins = n_bins
    def _setup(self):
        self._ready = True # a real encoder loads weights here
    def _check_input_types(self, batch):
        for item in batch:
            if not isinstance(item, types.Sound):
                raise ValueError(f"{type(self).__name__} takes types.Sound, got {type(item).__name__}")
    def _encode(self, batch) -> list[types.SoundEmbedding]:
        out = []
        for sound in batch:
            slices = np.array_split(sound.waveform.astype(np.float32), self.n_bins)
            vec = np.array([[float(np.sqrt(np.mean(s ** 2) + 1e-12)) for s in slices]], dtype=np.float32)
            vec /= np.linalg.norm(vec) + 1e-9
            out.append(types.SoundEmbedding(
                embedding=vec,
                timestamps=np.array([[0.0, sound.context.length / sound.context.sample_rate]], dtype=np.float32),
                context=sound.context))
        return out

class SpectralProfileEncoder(encoder_lib.MultiModalEncoder):
    """Contender: mean log-magnitude spectrum pooled into `n_bands` bands. Describes timbre."""
    def __init__(self, n_bands: int = 16, frame: int = 512):
        super().__init__()
        self.n_bands, self.frame = n_bands, frame
    def _setup(self):
        self._window = np.hanning(self.frame).astype(np.float32)
    def _check_input_types(self, batch):
        for item in batch:
            if not isinstance(item, types.Sound):
                raise ValueError(f"{type(self).__name__} takes types.Sound, got {type(item).__name__}")
    def _encode(self, batch) -> list[types.SoundEmbedding]:
        out = []
        for sound in batch:
            w = sound.waveform.astype(np.float32)
            n_frames = max(1, len(w) // self.frame)
            spectra = [np.abs(np.fft.rfft(w[i * self.frame:(i + 1) * self.frame] * self._window))
                       for i in range(n_frames)]
            mean_spectrum = np.log1p(np.mean(spectra, axis=0))
            vec = np.array([[float(b.mean()) for b in np.array_split(mean_spectrum, self.n_bands)]],
                           dtype=np.float32)
            vec /= np.linalg.norm(vec) + 1e-9
            out.append(types.SoundEmbedding(
                embedding=vec,
                timestamps=np.array([[0.0, sound.context.length / sound.context.sample_rate]], dtype=np.float32),
                context=sound.context))
        return out

@section("2. The encoder contract: three methods, and the framework does the rest")
def encoder_contract():
    print(" MultiModalEncoder abstract methods a subclass must implement:")
    for name in sorted(encoder_lib.MultiModalEncoder.__abstractmethods__):
        print(f" {name}")
    print(" final (framework-owned, do not override): setup(), encode()")
    t = np.arange(SR) / SR
    fade = np.exp(-2.5 * t).astype(np.float32) # a decaying note, so the envelope is not flat
    sound = types.Sound(waveform=(0.5 * fade * np.sin(2 * np.pi * 440 * t)).astype(np.float32),
                        context=types.SoundContextParams(id="demo_000", sample_rate=SR, length=SR))
    for enc in (EnergyEnvelopeEncoder(), SpectralProfileEncoder()):
        enc.setup()
        emb = enc.encode([sound])[0]
        stats = emb.encoding_stats # attached by encode(), not by our code
        print(f"\n {type(enc).__name__:24s} -> {emb.embedding.shape} {emb.embedding.dtype}"
              f" output_type={enc.output_type().__name__}")
        print(f" {'':24s} EncodingStats(input={stats.input_size_bytes:,} B, "
              f"embedding={stats.embedding_size_bytes} B, flops={stats.flops})")
        print(f" {'':24s} first 6 dims: {np.round(emb.embedding[0][:6], 3)}")
    print("\n The envelope encoder sees the note decay; the spectral encoder sees one peak at 440 Hz.")
    try:
        EnergyEnvelopeEncoder().encode(["not a Sound"])
    except ValueError as e:
        print(f"\n wrong input type is caught by _check_input_types: {e}")
    return "two encoders satisfying MultiModalEncoder"
encoder_contract()
การสร้าง encoder ทำได้โดยการสืบทอดจาก MultiModalEncoder และ実装เมทริกซ์สามอย่าง ได้แก่ _setup สำหรับโหลดโมเดล, _check_input_types สำหรับตรวจสอบอินพุต และ _encode สำหรับประมวลผล batch ในตัวอย่างนี้ EnergyEnvelopeEncoder จะจับเฉพาะระดับพลังงานเสียง (ความดัง) ในขณะที่ SpectralProfileEncoder จะจับข้อมูลทางสเปกตรัม (timbre) ซึ่งเมื่อทดสอบกับโน้ตที่ค่อยๆ เบาลง ทั้งสองตัวจะแสดงผลลัพธ์ที่สะท้อนคุณสมบัติที่แตกต่างกันอย่างชัดเจน
CLASSES = ["tone", "chirp", "noise"]
N_PER_CLASS = 12
def synthesize(kind: str, index: int, take: int) -> types.Sound:
    """One second of audio. `take` 0 is the document, take 1 is a noisier recording of the SAME clip.
    Two cues are deliberately separated: the spectrum says which class it is, and the amplitude
    envelope - drawn per item, independent of class - says which item it is.
    """
    item = np.random.default_rng(1000 + CLASSES.index(kind) * 100 + index)
    control = 0.25 + 0.75 * item.random(8)
    envelope = np.interp(np.linspace(0, 7, SR), np.arange(8), control).astype(np.float32)
    t = np.arange(SR) / SR
    if kind == "tone":
        w = np.sin(2 * np.pi * (380 + 80 * item.random()) * t)
    elif kind == "chirp":
        f0, f1 = 200 + 50 * item.random(), 3200 + 400 * item.random()
        w = np.sin(2 * np.pi * (f0 * t + 0.5 * (f1 - f0) * t ** 2))
    else:
        w = item.standard_normal(SR)
    w /= np.sqrt(np.mean(w ** 2)) + 1e-9 # unit RMS: the envelope is the only loudness cue
    take_rng = np.random.default_rng(50_000 + take * 10_000 + CLASSES.index(kind) * 100 + index)
    w = (0.4 + 0.2 * take_rng.random()) * envelope * (w + 0.02 * take_rng.standard_normal(SR))
    return types.Sound(waveform=w.astype(np.float32), context=types.SoundContextParams(
        id=f"{kind}_{index:02d}" + ("" if take == 0 else "_take2"), sample_rate=SR,
        length=SR, language="en_us", text=kind))

@section("3. A synthetic corpus, encoded into MSEB embedding caches")
def build_corpus():
    corpus = [synthesize(k, i, 0) for k in CLASSES for i in range(N_PER_CLASS)]
    queries = [synthesize(k, i, 1) for k in CLASSES for i in range(N_PER_CLASS)]
    labels = {s.context.id: s.context.text for s in corpus + queries}
    print(f" {len(corpus)} documents + {len(queries)} second takes of the same clips,"
          f" {len(CLASSES)} classes, 1.0s each @ {SR} Hz")
    caches, query_caches = {}, {}
    for enc in (EnergyEnvelopeEncoder(), SpectralProfileEncoder()):
        enc.setup()
        embeddings = enc.encode(corpus) # one batched call, like a real runner
        caches[type(enc).__name__] = {e.context.id: e for e in embeddings}
        query_caches[type(enc).__name__] = {e.context.id: e for e in enc.encode(queries)}
        matrix = np.vstack([e.embedding for e in embeddings])
        within, between = [], []
        for i in range(len(corpus)):
            for j in range(i + 1, len(corpus)):
                sim = float(matrix[i] @ matrix[j])
                (within if labels[corpus[i].context.id] == labels[corpus[j].context.id] else between).append(sim)
        print(f" {type(enc).__name__:24s} cache of {len(embeddings)} embeddings, dim {matrix.shape[1]}"
              f" mean cosine: same-class {np.mean(within):.3f} vs other-class {np.mean(between):.3f}"
              f" (gap {np.mean(within) - np.mean(between):+.3f})")
    print("\n Read that gap as a prediction: only the spectral encoder separates the classes at all.")
    print(" Steps 4-6 check whether the evaluators agree - and whether the gap is the whole story.")
    globals().update(CORPUS=corpus, QUERIES=queries, LABELS=labels, CACHES=caches, QCACHES=query_caches)
    return f"{len(corpus)} documents + {len(queries)} queries encoded by 2 encoders"
build_corpus()
เราสร้างคลังข้อมูลสังเคราะห์ 36 รายการ แบ่งเป็นสองเวอร์ชันคือเอกสารต้นฉบับและไฟล์เสียงที่มีเสียงรบกวน โดยแยกสัญญาณสเปกตรัม (ระบุประเภทเสียง) และ amplitude envelope (ระบุอัตลักษณ์คลิป) ออกจากกันอย่างจงใจ จากการวัดค่า cosine similarity เบื้องต้นพบว่ามีเพียง SpectralProfileEncoder เท่านั้นที่แยกประเภทเสียงได้ ซึ่งเป็นจุดที่เราจะทดสอบต่อในขั้นตอนการประเมินผล
def class_prototypes(cache, labels):
    """Class embedding table (C, D): the mean unit vector of each class, as the evaluator's `weights`."""
    rows = []
    for name in CLASSES:
        vecs = np.vstack([cache[i].embedding for i in cache if labels[i] == name])
        mean = vecs.mean(axis=0)
        rows.append(mean / (np.linalg.norm(mean) + 1e-9))
    return np.vstack(rows).astype(np.float32)

@section("4. ClassificationEvaluator: prototypes in, Score objects out")
def classification():
    table, example = {}, None
    for name, cache in CACHES.items():
        evaluator = classification_evaluator.ClassificationEvaluator(
            class_labels=CLASSES,
            weights=class_prototypes(cache, LABELS),
            distance_fn=evaluator_lib.dot_product, # embeddings are L2-normalised -> cosine
            top_k_value=2,
        )
        predictions = evaluator.compute_predictions(cache) # {id: per-class score vector}
        references = [classification_evaluator.ClassificationReference(i, LABELS[i]) for i in cache]
        table[name] = {s.metric: s.value for s in evaluator.compute_metrics(predictions, references)}
        if name == "SpectralProfileEncoder":
            key = next(iter(predictions))
            example = (key, np.round(list(predictions[key]), 3))
    metric_names = list(next(iter(table.values())))[:6]
    print(f" {'encoder':26s}" + "".join(f"{m[:14]:>16s}" for m in metric_names))
    for name, row in table.items():
        print(f" {name:26s}" + "".join(f"{row[m]:16.3f}" for m in metric_names))
    print(f"\n compute_predictions returns one raw score per class, e.g. {example[0]!r} -> {example[1]}")
    print(f" ({CLASSES} - the argmax is the prediction, and top_k_value=2 also scores Top-2 Accuracy.)")
    print(" compute_metrics turns those into types.Score objects, which is what the leaderboard stores.")
    for name, row in table.items():
        BENCH.setdefault(name, {})["Accuracy"] = row["Accuracy"]
    winner = max(table, key=lambda k: table[k]["Accuracy"])
    return "Accuracy: " + ", ".join(f"{k} {v['Accuracy']:.3f}" for k, v in table.items()) + f" (winner {winner})"
classification()
ClassificationEvaluator จะจำแนกประเภทเสียงโดยใช้ class prototypes เป็นค่าน้ำหนัก ในภารกิจนี้ SpectralProfileEncoder สามารถจำแนกประเภทได้แม่นยำ 100% ตามที่คาดไว้ ขณะที่ EnergyEnvelopeEncoder ทำได้เพียงเล็กน้อยเท่านั้น โดยระบบจะประเมินผลออกมาเป็นออบเจกต์ Score ซึ่งพร้อมสำหรับการจัดลำดับในลีดเดอร์บอร์ด
@section("5. ClusteringEvaluator: no labels at encode time, V-measure at score time")
def clustering():
    evaluator = clustering_evaluator.ClusteringEvaluator()
    examples = [clustering_evaluator.ClusteringExample(sound_id=i, label=LABELS[i])
                for i in next(iter(CACHES.values()))]
    print(f" {len(examples)} examples, KMeans with k = {len(CLASSES)} (inferred from the labels)")
    for name, cache in CACHES.items():
        np.random.seed(0) # MiniBatchKMeans takes no random_state here:
        scores = evaluator(cache, examples) # it falls back to NumPy's global RNG, so pin that
        BENCH.setdefault(name, {})["VMeasure"] = scores[0].value
        print(f" {name:26s} {scores[0].metric:12s} {scores[0].value:6.3f}"
              f" [{scores[0].min}, {scores[0].max}] :: {scores[0].description}")
    print("\n V-measure is the harmonic mean of homogeneity and completeness: 1.0 means the clusters")
    print(" recover the classes exactly, 0.0 means they carry no information about them. Note how much")
    print(" harsher it is on the envelope encoder than accuracy was - clustering gets no labels to lean on.")
    return ", ".join(f"{k} V={v['VMeasure']:.3f}" for k, v in BENCH.items())
clustering()
ในภารกิจการจัดกลุ่ม (Clustering) จะมีความท้าทายมากขึ้นเพราะโมเดลต้องทำงานโดยไม่มีเลเบลกำกับ ระบบใช้ V-measure ในการประเมิน ซึ่งแสดงให้เห็นว่าช่องว่างความสามารถระหว่าง encoder ทั้งสองกว้างขึ้นกว่าเดิมอย่างชัดเจน เนื่องจากตัวประเมินผลแบบไม่มีผู้สอน (unsupervised) ไม่สามารถอาศัยสัญญาณจางๆ ที่ใช้ได้ในการจำแนกประเภท
@section("6. RetrievalEvaluator: index the corpus, query it with a second take, score the ranking")
def retrieval():
    print(" Task: each query is a NOISIER RECORDING OF ONE DOCUMENT, and exactly one document is correct.")
    print(" This is identity, not category - a different question from steps 4 and 5.\n")
    out = {}
    for name, cache in CACHES.items():
        doc_ids = list(cache)
        docs = np.vstack([cache[i].embedding for i in doc_ids]).astype(np.float32)
        queries = QCACHES[name]
        searcher = retrieval_evaluator.BruteForceSearcher(candidates=docs, num_neighbors=10)
        evaluator = retrieval_evaluator.RetrievalEvaluator(searcher=searcher, id_by_index_id=doc_ids, top_k=5)
        predictions = evaluator.compute_predictions(queries)
        references = [retrieval_evaluator.RetrievalReferenceId(
            sound_id=q, reference_id=q.removesuffix("_take2")) for q in queries]
        out[name] = {s.metric: s.value for s in evaluator.compute_metrics(predictions, references)}
        q0 = next(iter(queries))
        top = [item["id"] for item in predictions[q0].items[:5]]
        print(f" top-5 for query {q0!r} under {name}:")
        print(f" {top}")
        print(f" correct document at rank {top.index(q0.removesuffix('_take2')) + 1}"
              f" | neighbours of the same class: {sum(LABELS[i] == LABELS[q0] for i in top)}/5\n")
    metric_names = ["MRR", "EM", "RecallAt5", "NDCG@10"]
    print(f" {'encoder':26s}" + "".join(f"{m:>14s}" for m in metric_names))
    for name, row in out.items():
        print(f" {name:26s}" + "".join(f"{row[m]:14.3f}" for m in metric_names))
    BENCH.setdefault(name, {})["MRR"] = row["MRR"]
    return ", ".join(f"{k} MRR={v['MRR']:.3f}" for k, v in out.items())
retrieval()
ผลลัพธ์ของ RetrievalEvaluator แสดงให้เห็นการสลับขั้วอย่างน่าสนใจ โดยในภารกิจนี้เป้าหมายคือการค้นหาอัตลักษณ์ของเสียง (Identity) ไม่ใช่ประเภท EnergyEnvelopeEncoder จึงทำคะแนนได้สมบูรณ์แบบเพราะ envelope ทำหน้าที่เสมือนลายนิ้วมือของคลิปเสียง ในขณะที่ SpectralProfileEncoder กลับทำอันดับได้แย่กว่าเพราะคลิปในคลาสเดียวกันดูคล้ายกันเกินไปสำหรับมัน
@section("7. The metric layer on its own: WER, CER, exact match, MRR, nDCG")
def metric_layer():
    truth = "the quick brown fox jumps over the lazy dog"
    for hypothesis in [truth, "the quick brown fox jumped over a lazy dog", "quick brown fox over lazy dog"]:
        werrors, wtotal = metrics.compute_word_errors(truth, hypothesis)
        cerrors, ctotal = metrics.compute_character_errors(truth, hypothesis)
        print(f" WER {werrors / wtotal:5.3f} ({werrors}/{wtotal} words) "
              f"CER {cerrors / ctotal:5.3f} ({cerrors}/{ctotal} chars) {hypothesis!r}")
    print("\n ranking metrics take (reference, ranked_ids):")
    ranked = ["doc_b", "doc_a", "doc_c", "doc_d"]
    for reference in ["doc_b", "doc_a", "doc_c", "doc_z"]:
        rank = ranked.index(reference) + 1 if reference in ranked else None
        print(f" reference {reference!r:8s} rank {str(rank):4s}"
              f" EM {metrics.compute_exact_match(reference, ranked):.1f}"
              f" MRR {metrics.compute_reciprocal_rank(reference, ranked):.3f}"
              f" nDCG@4 {metrics.compute_ndcg_at_k(reference, ranked, k=4):.3f}")
    a = np.random.default_rng(1).standard_normal((8, 4)).astype(np.float32)
    for label, b in [("identical", a), ("noisy", a + 0.1 * np.random.default_rng(2).standard_normal(a.shape))]:
        lp = metrics.compute_lp_norm(a, b, p=2)
        dtw = metrics.compute_dynamic_time_warping_distance(a, b)
        print(f" {label:10s} L2 {json.dumps({k: round(float(v), 3) for k, v in lp.items()})}"
              f" DTW {json.dumps({k: round(float(v), 3) for k, v in dtw.items()})}")
    return "WER/CER, EM/MRR/nDCG, Lp and DTW distances"
metric_layer()
เลเยอร์เมทริกซ์ (Metric Layer) คือส่วนที่ใช้งานร่วมกันในหลายภารกิจ เช่น WER/CER สำหรับข้อความ, เมทริกซ์การจัดอันดับอย่าง MRR และ nDCG รวมถึงระยะห่างในพื้นที่ embedding เช่น L2 และ Dynamic Time Warping (DTW) สิ่งสำคัญคือต้องเข้าใจรูปแบบข้อมูลที่แต่ละฟังก์ชันรับ เพื่อให้การประเมินผลถูกต้องแม่นยำที่สุด
@section("8. SegmentationEvaluator: scoring WHAT was said and WHERE, separately")
def segmentation():
    evaluator = segmentation_evaluator.SegmentationEvaluator(tau=0.05)
    TERMS = [("weather", 0.00, 0.30), ("in", 0.30, 0.65), ("boston", 0.65, 1.00)]
    truth = [segmentation_evaluator.Segment(embedding=term, start_time=s, end_time=e, confidence=1.0)
             for term, s, e in TERMS]
    references = [segmentation_evaluator.SegmentationReference(example_id="utt_0", segments=truth)]
    def prediction(spans):
        return {"utt_0": types.SoundEmbedding(
            embedding=np.array([term for term, _, _ in spans]), # N strings
            timestamps=np.array([[s, e] for _, s, e in spans], dtype=np.float32), # N [start, end]
            context=types.SoundContextParams(id="utt_0", sample_rate=SR, length=SR),
            scores=np.ones(len(spans), dtype=np.float32))} # confidences
    candidates = {
        "exact": TERMS,
        "50 ms out": [("weather", 0.00, 0.28), ("in", 0.28, 0.67), ("boston", 0.67, 1.00)],
        "right words, wrong places": [("weather", 0.00, 0.45), ("in", 0.45, 0.80), ("boston", 0.80, 1.00)],
        "right places, wrong words": [("weather", 0.00, 0.30), ("on", 0.30, 0.65), ("austin", 0.65, 1.00)],
    }
    shown = ["TimestampsAccuracy", "EmbeddingsAccuracy", "TimestampsAndEmbeddingsAccuracy", "WordErrorRate", "mAP"]
    for label, spans in candidates.items():
        result = evaluator.compute_scores(prediction(spans), references)
        scores = {s.metric: s.value for s in evaluator.compute_metrics(result)}
        print(f" {label:28s}" + "".join(f"{scores[m]:15.3f}" for m in shown))
    return "boundary + term scoring at tau=50 ms"
segmentation()
SegmentationEvaluator จะให้คะแนนแยกกันระหว่าง "เนื้อหา" และ "ตำแหน่ง" ที่พูดผ่านรูปแบบการส่ง SoundEmbedding เป็นสตริง ภารกิจนี้ช่วยให้เห็นความแตกต่างระหว่างความผิดพลาดด้านจังหวะเวลาและความผิดพลาดด้านการจำแนกคำ โดยมีค่าความคลาดเคลื่อนยอมรับได้ (tau) เพื่อให้การประเมินมีความยืดหยุ่นตามการใช้งานจริง
@section("9. TaskMetadata and a leaderboard that disagrees with itself")
def task_metadata():
    cache = CACHES["SpectralProfileEncoder"]
    evaluator = classification_evaluator.ClassificationEvaluator(
        class_labels=CLASSES, weights=class_prototypes(cache, LABELS), top_k_value=2)
    references = [classification_evaluator.ClassificationReference(i, LABELS[i]) for i in cache]
    scores = [s for s in evaluator.compute_metrics(evaluator.compute_predictions(cache), references)
              if s.metric in ("Accuracy", "Weighted F1-Score")]
    metadata = types.TaskMetadata(
        name="SyntheticToneClassification",
        description="Three-way classification of synthetic tones, chirps and noise",
        reference="https://github.com/google-research/mseb",
        type="Classification",
        category="sound",
        main_score="Accuracy",
        revision="1",
        dataset=types.Dataset(path="synthetic/in-notebook", revision="1"),
        scores=scores,
        eval_splits=["test"],
        eval_langs=["en_us"],
    )
    columns = ["Accuracy", "VMeasure", "MRR"]
    for name, row in BENCH.items():
        print(f" {name:26s}" + "".join(f"{row[c]:12.3f}" for c in columns)
              + (" timbre -> class" if "Spectral" in name else " loudness over time -> identity"))
    return f"TaskMetadata + {len(BENCH)} encoders x {len(columns)} task families"
task_metadata()
ในท้ายที่สุด เมื่อรวบรวมข้อมูลผ่าน TaskMetadata และเปรียบเทียบผลลัพธ์ในตารางเดียว จะเห็นว่าผู้ชนะในแต่ละหมวดหมู่นั้นไม่เหมือนกัน นี่คือเหตุผลสำคัญว่าทำไม benchmark ต้องมีความหลากหลาย (Massive) เพราะคะแนนหัวข้อเดียวไม่สามารถตัดสินคุณภาพของ sound embedding ได้ครอบคลุมทุกแง่มุม การรันการทดสอบตั้งแต่ต้นจนจบนี้พิสูจน์ให้เห็นว่าความต้องการพื้นฐานเพียงสามวิธีก็เพียงพอที่จะเชื่อมต่อเข้ากับมาตรฐาน MSEB ได้อย่างสมบูรณ์
การนำไปใช้ต่อในลำดับถัดไปคือการสลับไปใช้ encoder จริง เช่น wav2vec หรือ Whisper แทนตัวทดสอบ และการรันภารกิจกับชุดข้อมูลจริงผ่าน mseb.runner เพื่อเปรียบเทียบผลลัพธ์กับลีดเดอร์บอร์ดสาธารณะของ Hugging Face ต่อไป
ความคิดเห็น (0)
เข้าสู่ระบบเพื่อร่วมแสดงความเห็น
สมัครสมาชิกมาเป็นคนแรกที่แสดงความเห็นกันเลยโบร