
Liquid AI เปิดตัว LFM3 โมเดล Multimodal เฉพาะทางขนาด 2B
LFM3 คือเจเนอเรชันใหม่ของ Liquid Foundation Models (LFMs) ที่ออกแบบมาเพื่อเป็นรากฐานสำหรับปัญญาประดิษฐ์เฉพาะทาง โดยการรวมความสามารถด้านข้อความ การมองเห็น เสียง omni และการตัดสินใจไว้บน backbone เดียวกัน ในขนาดพารามิเตอร์เพียง 2B ช่วยให้ผู้ใช้สามารถเลือกโมเดลตามรูปแบบที่ต้องการ นำมา fine-tune ด้วยข้อมูลเฉพาะทางบน GPU เพียงตัวเดียว และ deploy ใช้งานบนอุปกรณ์ได้ทันที
LFM3 นำเสนอการเปลี่ยนแปลงหลัก 4 ประการเมื่อเทียบกับตระกูล LFM2 รุ่นก่อนหน้า:
- ความสามารถต่อพารามิเตอร์ที่มากขึ้น: สถาปัตยกรรม tri-hybrid ใหม่ช่วยให้ LFM3-1.7B มีประสิทธิภาพเหนือกว่า LFM2.5-2.6B แม้จะใช้พารามิเตอร์น้อยกว่าถึง 35%
- ทุก modality บน backbone เดียว: โมเดลระดับ 2B ทั้ง 6 รูปแบบถูกฝึกมาจาก LFM3-1.7B-Base ซึ่งรวมถึงโมเดล omni รุ่นแรกและการรองรับวิดีโอ
- สร้างมาเพื่อ edge: โมเดลข้อความใช้หน่วยความจำเพียง 1 GB ที่ความแม่นยำ 4-bit พร้อม context window ขนาด 256K ช่วยให้ agent ทำงานบนอุปกรณ์ (on-device) ได้อย่างลื่นไหล
- สร้างมาเพื่อความเฉพาะทาง: ทุกโมเดลรองรับการ fine-tune บน GPU เพียงตัวเดียว เพื่อปรับให้เข้ากับข้อมูลและสภาพแวดล้อมการ deploy เฉพาะด้าน
วิธีที่เราสร้าง backbone ที่แสดงออกได้มากขึ้น
LFM2 เคยพิสูจน์แล้วว่าการผสมผสาน short convolutions และ attention ทำงานได้เร็วบนอุปกรณ์โดยไม่เสียคุณภาพ สำหรับ LFM3 ทีมงานได้ใช้การค้นหาสถาปัตยกรรมแบบ hardware-in-the-loop เพื่อออกแบบใหม่ให้เหมาะกับงานประเภท agentic ที่ต้องการความเร็วในบริบทที่ยาว ปัจจุบันรองรับอุปกรณ์และ backend ถึง 14 รูปแบบ ตั้งแต่ Raspberry Pi 5 ไปจนถึง Qualcomm Hexagon NPU
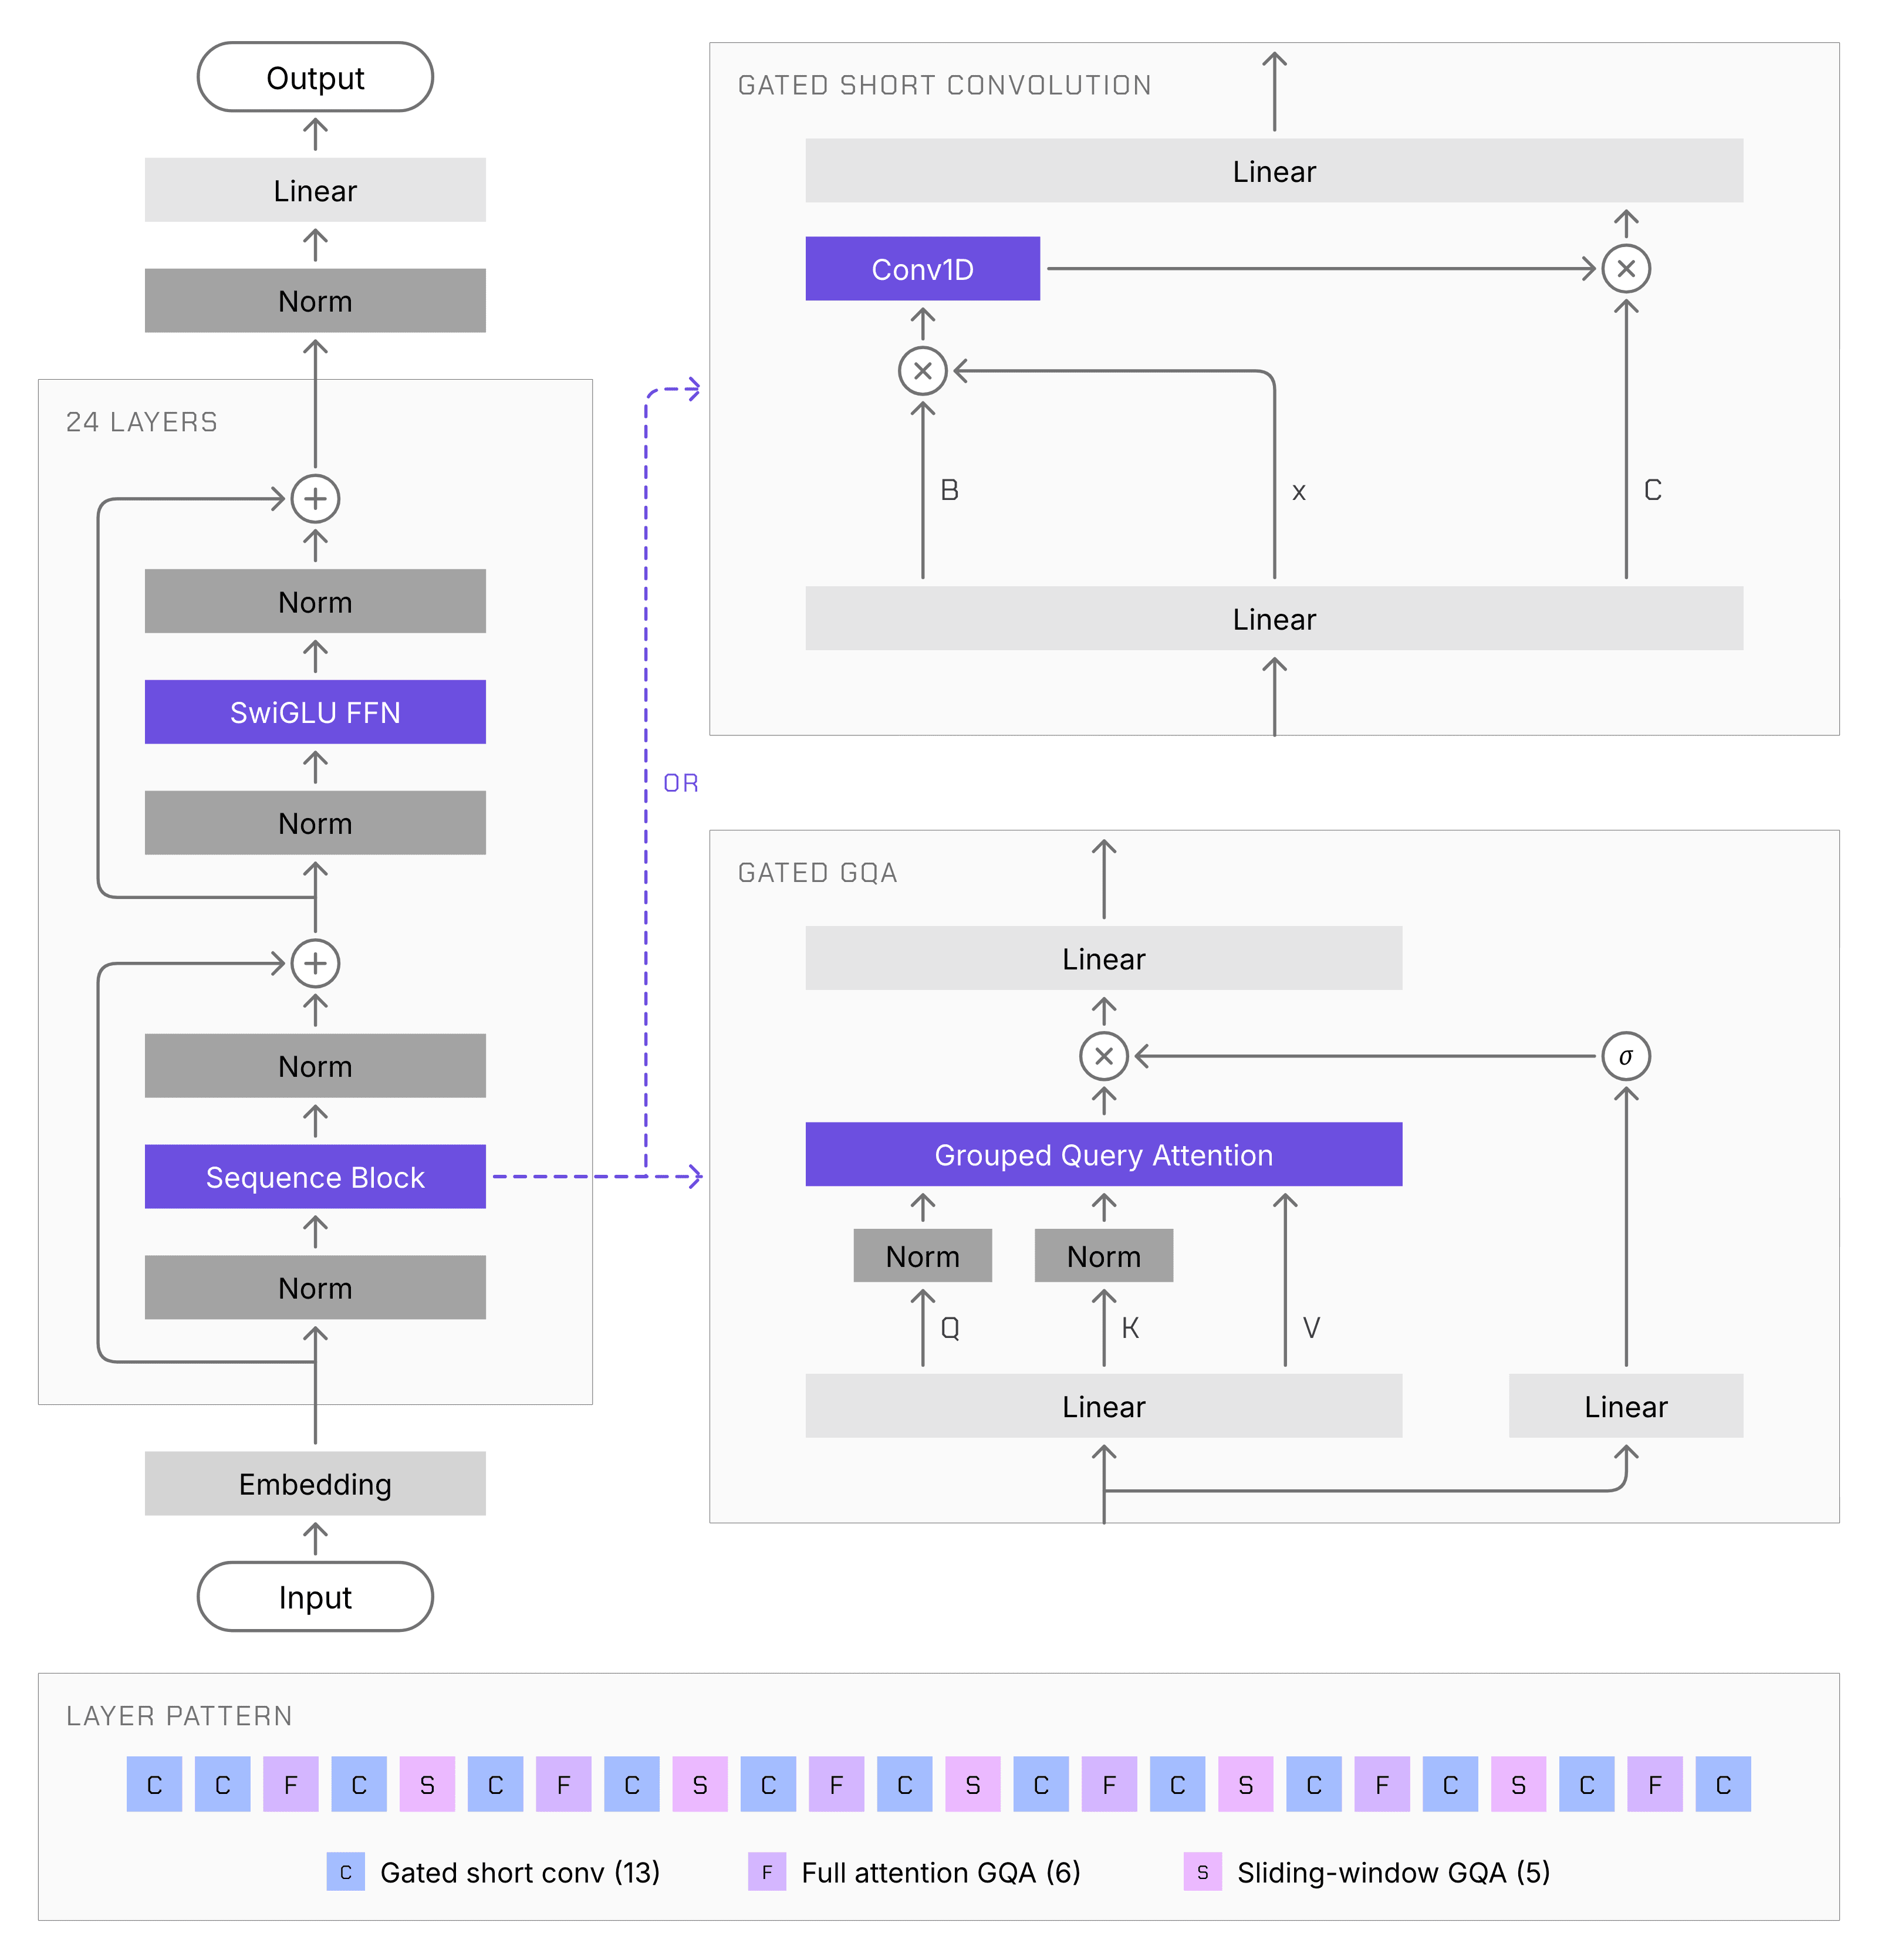
LFM3-1.7B-Base ประกอบด้วย 24 เลเยอร์และการเปลี่ยนแปลงหลัก 4 ส่วน:
- Tri-hybrid layer mix: การผสมผสาน 13 gated short convolutions, 5 sliding-window attention (SWA) และ 6 global attention layers โดยขยาย kernel size ของ convolutions เป็น 7
- Head-wise gated attention: ใช้ sigmoid gate ปรับขนาด output ของแต่ละ head เพื่อยับยั้ง activation outliers ที่ส่งผลเสียต่อ quantization
- Partial RoPE: เลเยอร์ global attention จะหมุนเฉพาะครึ่งหนึ่งที่มีความถี่สูงสุดของแต่ละ head เพื่อให้เหลืออีกครึ่งหนึ่งจับคู่ตามเนื้อหาโดยไม่คำนึงถึงระยะทาง
- Sandwich norm: ทำ normalization ทั้ง input และ output ในแต่ละบล็อกเพื่อรักษาขนาด activations ให้เหมาะสม
ในด้านประสิทธิภาพ LFM3-1.7B-Base ถูกฝึกด้วย 22T tokens และขยาย context window เป็น 256K tokens ผ่านขั้นตอน mid-training ด้วยข้อมูลที่เน้น agentic traces และ tool calls ทำให้ประมวลผลบริบทขนาด 8K tokens ได้เร็วขึ้นกว่าเดิม 25%
หนึ่ง backbone สำหรับหกโมเดล
โมเดล LFM3 ทุกตัวแตกแขนงมาจาก LFM3-1.7B-Base เพื่อให้ผู้ใช้เลือกตัวที่เหมาะกับ input เฉพาะทางแทนการใช้โมเดลทั่วไปขนาดใหญ่
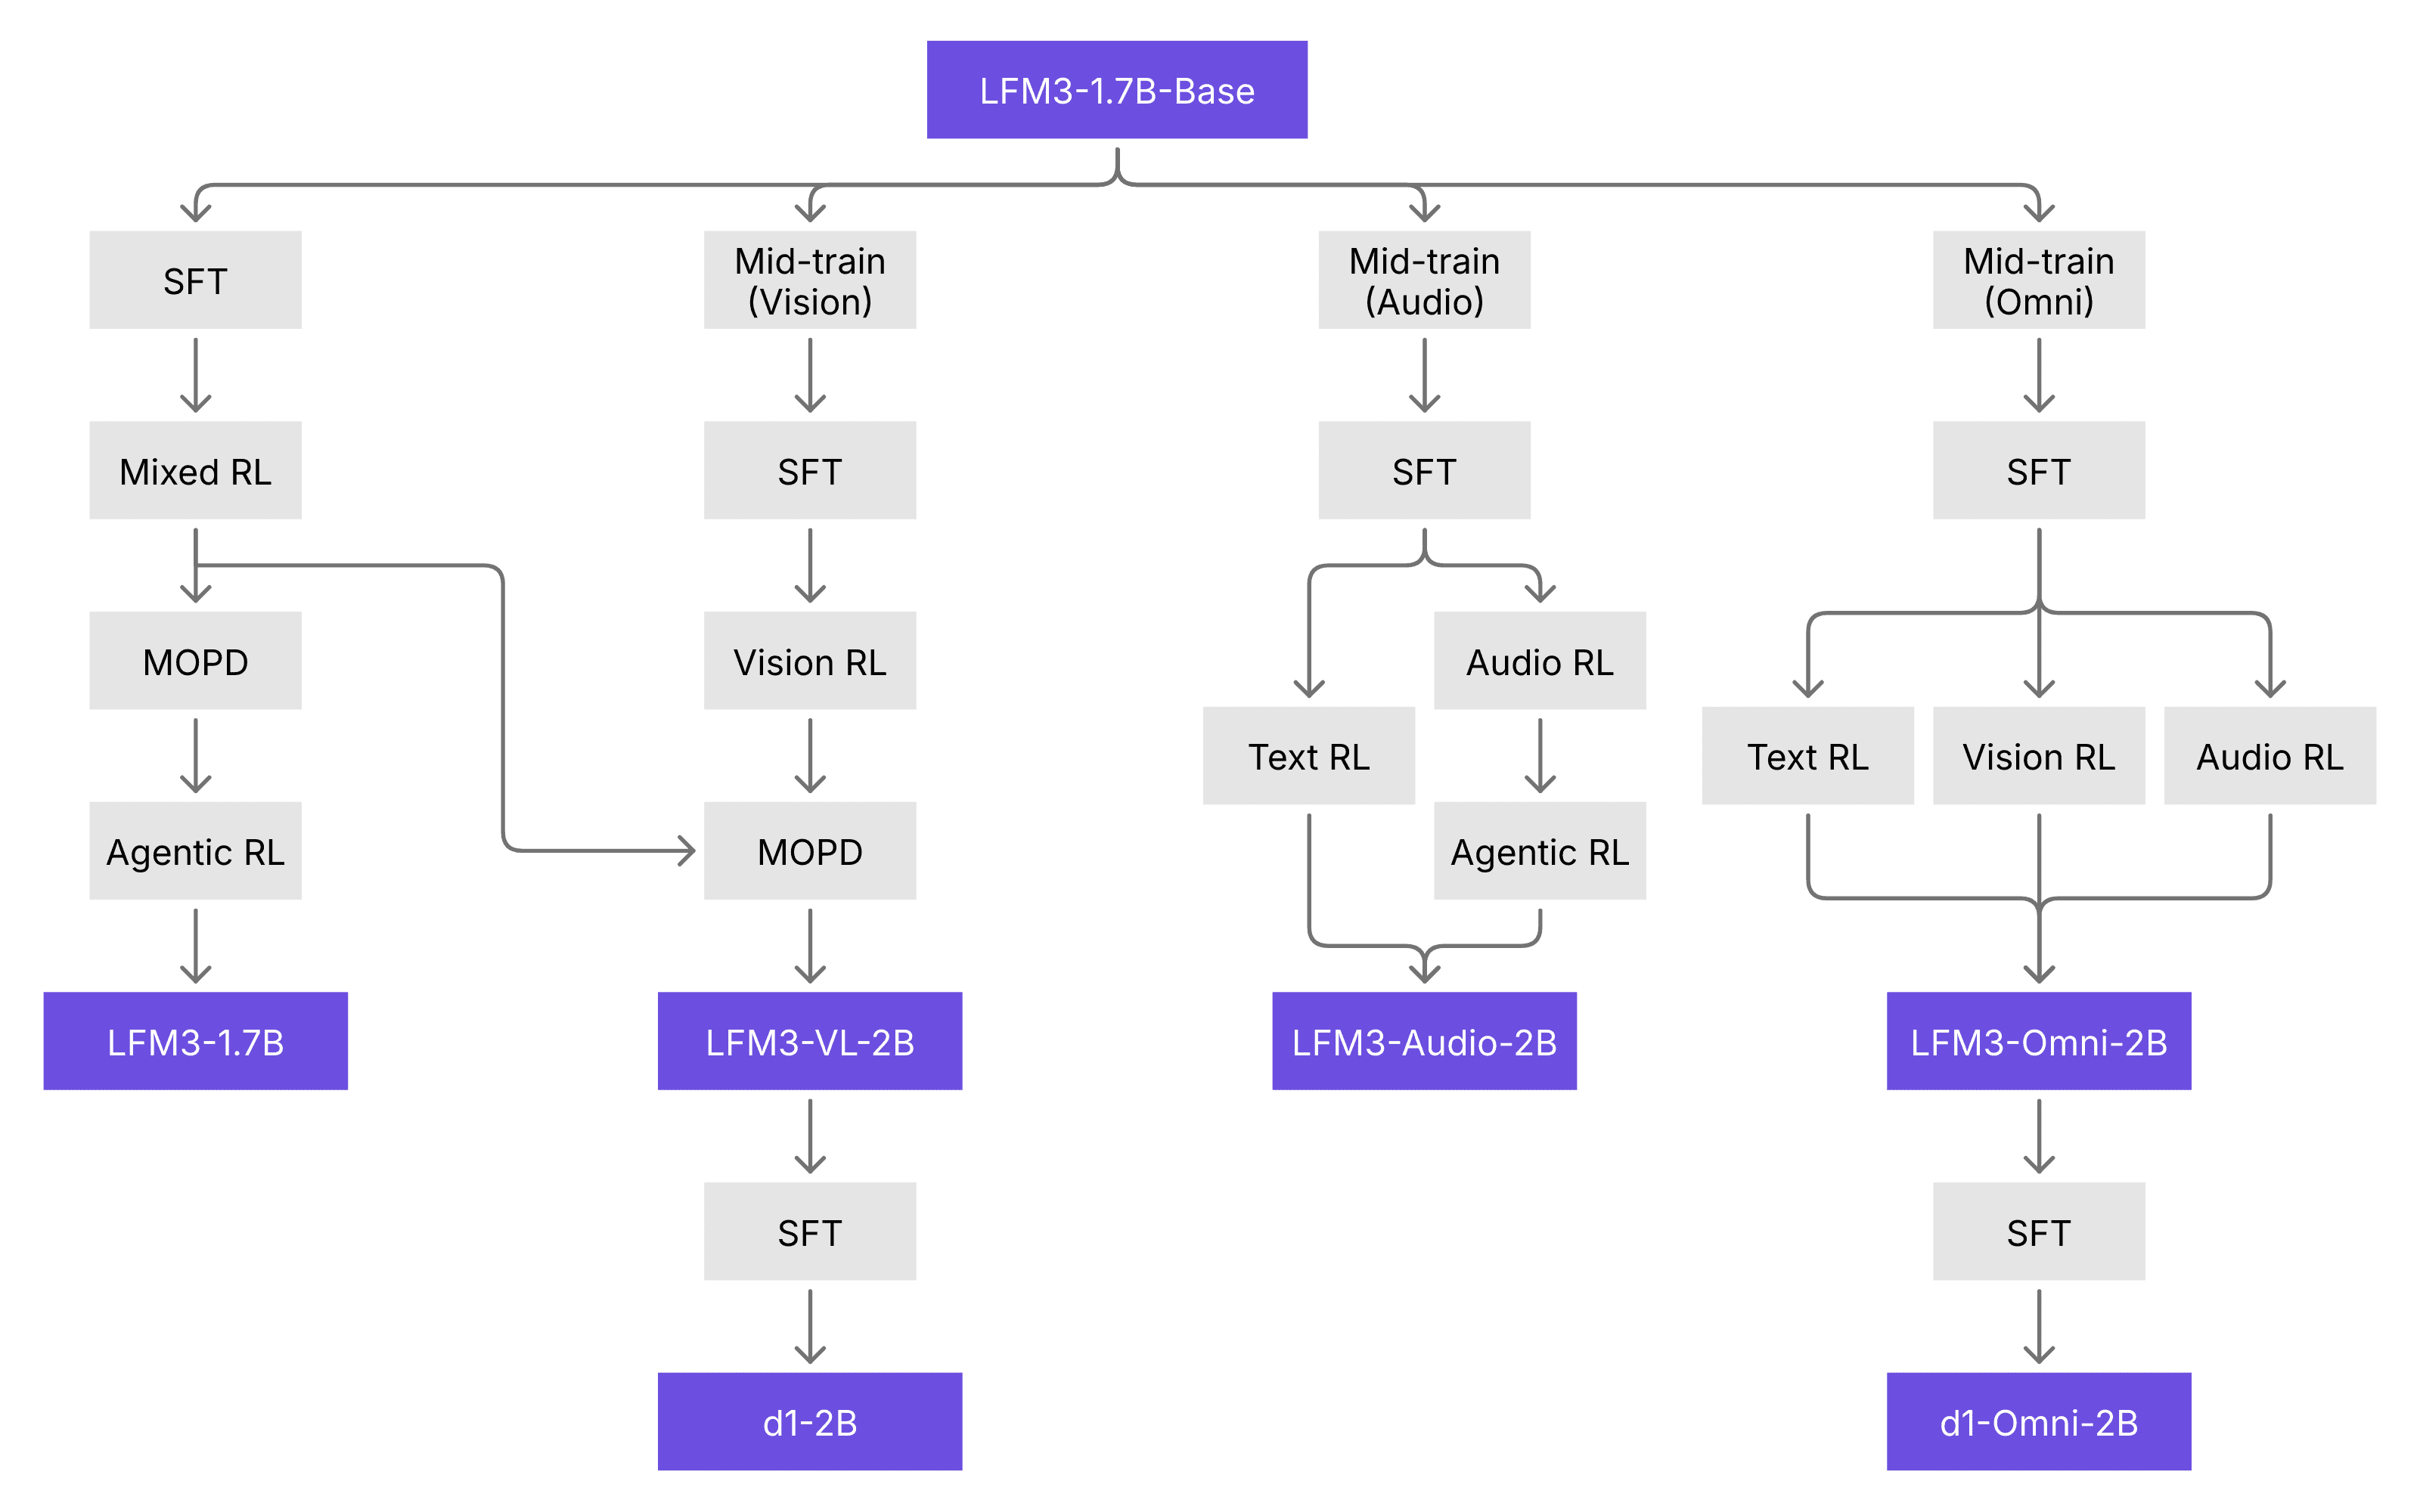
| โมเดล | Input | Output | สร้างบน |
|---|---|---|---|
| LFM3-1.7B | ข้อความ | ข้อความ | LFM3-1.7B-Base |
| LFM3-VL-2B | ข้อความ, รูปภาพ, วิดีโอ | ข้อความ | LFM3 backbone + vision encoder |
| LFM3-Audio-2B | ข้อความ, เสียง | ข้อความ, คำพูด | LFM3 backbone + audio encoder, audio decoder, และ LiquidCodec |
| LFM3-Omni-2B | ข้อความ, รูปภาพ, วิดีโอ, เสียง | ข้อความ, คำพูด | LFM3 backbone + vision และ audio encoders และ audio decoder |
| d1-2B | ข้อความ, รูปภาพ, วิดีโอ | คำตอบที่ผ่านการปรับจูนความแม่นยำ | LFM3-VL-2B |
| d1-omni-2B | ข้อความ, รูปภาพ, วิดีโอ, เสียง | คำตอบที่ผ่านการปรับจูนความแม่นยำ | LFM3-Omni-2B |
โมเดลด้านภาพและเสียงยังใช้ encoder ใหม่ที่พัฒนาขึ้นเอง โดย vision encoder ใช้พลังงานน้อยกว่า SigLIP2 ถึง 3 เท่า ส่วน audio encoder และ LiquidCodec สามารถประมวลผลคำพูดได้เร็วกว่าเวลาจริง 87 เท่าบน Apple M4 Max
วิธีใช้งานโมเดล LFM3
โมเดลทำงานผ่าน transformers โดยแต่ละรุ่นมีความโดดเด่นในงานที่ต่างกันไป
LFM3-1.7B
เหมาะสำหรับ local agents และการทำ tool calling โดยมีประสิทธิภาพในงานด้าน agentic บน WebArena-Verified สูงถึง 38.42 คะแนน แซงหน้า Qwen3.5-9B ในงานที่ซับซ้อน รายละเอียดเพิ่มเติมที่ LFM3-1.7B model card
ติดตั้ง transformers เวอร์ชันล่าสุดเพื่อเริ่มต้น:
pip install -U transformersตัวอย่างการโหลดและรันโมเดล:
from transformers import pipeline

generator = pipeline(
    "text-generation",
    model="LiquidAI/LFM3-1.7B",
    trust_remote_code=True,
)

messages = [{"role": "user", "content": "What is C. elegans?"}]
output = generator(
    messages,
    do_sample=True,
    temperature=0.1,
    top_k=50,
    repetition_penalty=1.1,
    max_new_tokens=2048,
)
print(output[0]["generated_text"][-1]["content"])
LFM3-VL-2B
ออกแบบมาเพื่อความเข้าใจภาพและวิดีโอบนอุปกรณ์ ให้เหตุผลเป็นขั้นตอนและระบุตำแหน่งวัตถุได้แม่นยำ โดยทำคะแนนเฉลี่ย 62 vision benchmarks ได้ถึง 71.4 คะแนน เทียบเท่า Gemma 4 12B ที่ใหญ่กว่าถึง 6 เท่า รายละเอียดที่ LFM3-VL-2B model card
import torch
from transformers import AutoModelForImageTextToText, AutoProcessor

model_id = "LiquidAI/LFM3-VL-2B"

model = AutoModelForImageTextToText.from_pretrained(model_id, dtype=torch.bfloat16, device_map="auto", trust_remote_code=True)
processor = AutoProcessor.from_pretrained(model_id, trust_remote_code=True)

messages = [
    {
        "role": "user",
        "content": [
            {"type": "image", "url": "https://placecats.com/300/200"},
            {"type": "text", "text": "Describe this image."},
        ],
    }
]

inputs = processor.apply_chat_template(
    messages,
    add_generation_prompt=True,
    tokenize=True,
    return_dict=True,
    return_tensors="pt",
).to(model.device)

with torch.inference_mode():
    output_ids = model.generate(
        **inputs,
        do_sample=True,
        temperature=0.1,
        top_k=50,
        repetition_penalty=1.1,
        max_new_tokens=16384,
    )

generated_ids = output_ids[:, inputs["input_ids"].shape[1] :]
print(processor.batch_decode(generated_ids, skip_special_tokens=True)[0])
LFM3-Audio-2B
รองรับ voice chat และการแปลภาษา 18 ภาษาบนอุปกรณ์ edge สามารถเปลี่ยนเสียงพูดเป็น tool calls ได้ทันทีพร้อมคุณภาพเสียงสังเคราะห์ที่สูงกว่ารุ่นเดิม รายละเอียดที่ LFM3-Audio-2B model card
import torch
import soundfile as sf
from transformers import AutoModelForMultimodalLM, AutoProcessor

model_id = "LiquidAI/LFM3-Audio-2B"
device = "cuda" if torch.cuda.is_available() else "cpu"
dtype = torch.bfloat16 if device == "cuda" else torch.float32

model = AutoModelForMultimodalLM.from_pretrained(
    model_id, dtype=dtype, device_map=device, trust_remote_code=True
).eval()
processor = AutoProcessor.from_pretrained(model_id, trust_remote_code=True)
codec = processor.audio_tokenizer.to(device=device).eval()
LFM3-Omni-2B
โมเดล All-in-one ที่มองเห็น ฟัง และพูดโต้ตอบได้ในตัวเดียว ช่วยลดความยุ่งยากในการใช้หลายโมเดลแยกกัน สามารถประมวลผลวิดีโอพร้อมเสียงได้เหนือกว่า Qwen2.5-Omni-7B ในหลายการทดสอบ รายละเอียดที่ LFM3-Omni-2B model card
d1-2B และ d1-omni-2B
เน้นการตัดสินใจที่มีโครงสร้าง รวดเร็ว และแม่นยำ (single forward pass) เหมาะสำหรับงานจัดการตั๋วสนับสนุนลูกค้าหรืออ่านค่าเอกสาร โดย d1-2B ทำคะแนนใน ImajevBench ได้สูงกว่า d1-3B เดิมอย่างมาก
import torch
from transformers import AutoModel

device = "cuda" if torch.cuda.is_available() else "mps" if torch.backends.mps.is_available() else "cpu"
dtype = torch.float32 if device == "cpu" else torch.bfloat16
model = AutoModel.from_pretrained("LiquidAI/d1-2B", trust_remote_code=True, dtype=dtype).to(device)

questions = {
    "refund": {"type": "noul", "instructions": "Is the customer asking for a refund?"},
    "team": {"type": "choice", "instructions": "Which team should handle this?",
             "criteria": {"billing": "Charges, refunds, invoices", "shipping": "Delivery and parcels",
                          "technical": "App or site faults"}},
    "topics": {"type": "choice", "multiple": True, "instructions": "Which topics does the message raise?",
               "criteria": {"billing": "Payments and charges", "delivery": "Shipping and parcels",
                            "login": "Signing in to the account"}},
    "urgency": {"type": "score", "instructions": "How urgent is this ticket?", "criteria": ["low", "medium", "high"]},
}
out = model.system_one("I was charged twice and my parcel never arrived. Please refund one charge.", questions)
Fine-tune LFM3 สำหรับงานของคุณ
LFM3 ถูกออกแบบให้เป็นโมเดลผู้เชี่ยวชาญเฉพาะทาง การ fine-tune ระยะสั้นสามารถเปลี่ยนให้มันทำงานเฉพาะด้านได้อย่างเชื่อถือได้ เช่น การสกัด JSON จากเอกสาร หรือการเรียนรู้ภาษาใหม่
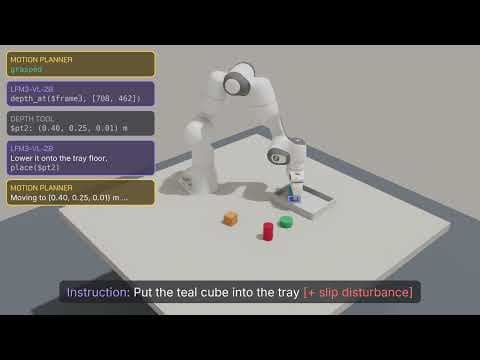
ตัวอย่างความสำเร็จคือการปรับแต่ง LFM3-VL-2B ให้เป็นโมเดลหุ่นยนต์ 3 รูปแบบ (VLA) ซึ่งสามารถสร้างชุดการทำงานได้ในเวลาไม่ถึง 50 ms บน Jetson AGX Orin พร้อมความสำเร็จเฉลี่ย 96.2% ในชุดทดสอบ LIBERO
ชมวิดีโอสาธิตการใช้งานหุ่นยนต์ได้ที่ วิดีโอสาธิตนี้
เริ่มต้นใช้งาน LFM3
โมเดล LFM3 ทั้งหมดเป็นแบบ open-weight พร้อมใช้งานแล้ว:
- ดาวน์โหลด: คอลเลกชัน LFM3 บน Hugging Face
- Fine-tune: ศึกษาขั้นตอนจาก fine-tuning notebooks
- การใช้งาน: คู่มือการรัน local agent ที่ docs.liquid.ai
การอ้างอิง
หากคุณใช้ผลงานนี้ โปรดอ้างอิงบล็อกการเปิดตัว:
@article{liquidAI2026LFM3,
  author = {Liquid AI},
  title = {Introducing LFM3: Every Modality for Specialized Intelligence},
  journal = {Liquid AI Blog},
  year = {2026},
  note = {www.liquid.ai/blog/lfm3},
}ความคิดเห็น (0)
เข้าสู่ระบบเพื่อร่วมแสดงความเห็น
สมัครสมาชิกมาเป็นคนแรกที่แสดงความเห็นกันเลยโบร